Chen Liu

Chen Liu

Postdoctoral Research Associate

Australian Artificial Intelligence Institute
University of Technology Sydney

About

I am a Postdoctoral Research Associate at the University of Technology Sydney (UTS), working with Prof. Ling Chen. I received my Ph.D. from The University of Queensland, supervised by Prof. Xin Yu.

My research focuses on agentic AI and multimodal learning. I am interested in how AI systems connect perception with reliable action: understanding sounds and visual scenes, grounding instructions in interfaces, and carrying out useful tasks in real-world environments.

My current work explores computer-use agents for long-horizon workflows and the diagnostic evaluation of multimodal foundation models. Previously, I developed object-centric audio-visual alignment methods for sounding-source segmentation. I have also worked with CSIRO Data61, NetEase Fuxi AI Lab and Alibaba Tongyi Lab.
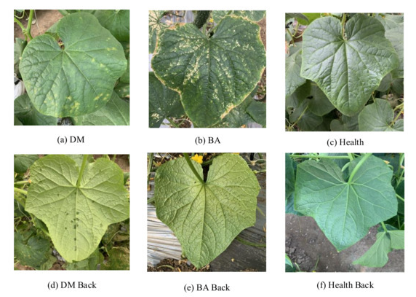
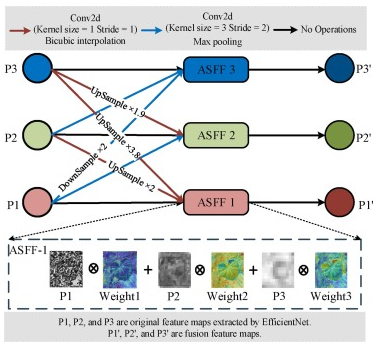
Selected work across agentic AI, multimodal understanding, audio-visual learning, 3D/4D generation, digital humans and agriculture engineering. * Equal contribution.

opengcua research figure

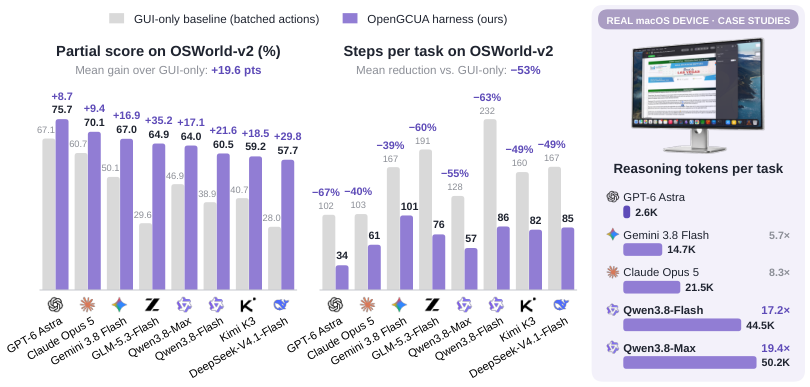
OpenGCUA: Toward a Fully Open Stack for Generalist Computer Use

Hanzhang Zhou, Long Li, Quyu Kong, Lei Wang, Panrong Tong, Long Chen, Tianyu Xia, Gongjie Zhang, Xu Zhang, Chen Liu, Jianan Zhang, Chenglin Cai, Zhengwen Zeng, Steven Hoi, Yue Wang

Technical report · 2026PaperProject

An open stack for generalist computer-use agents that combine visual interaction with programmatic tools.

uiins research figure

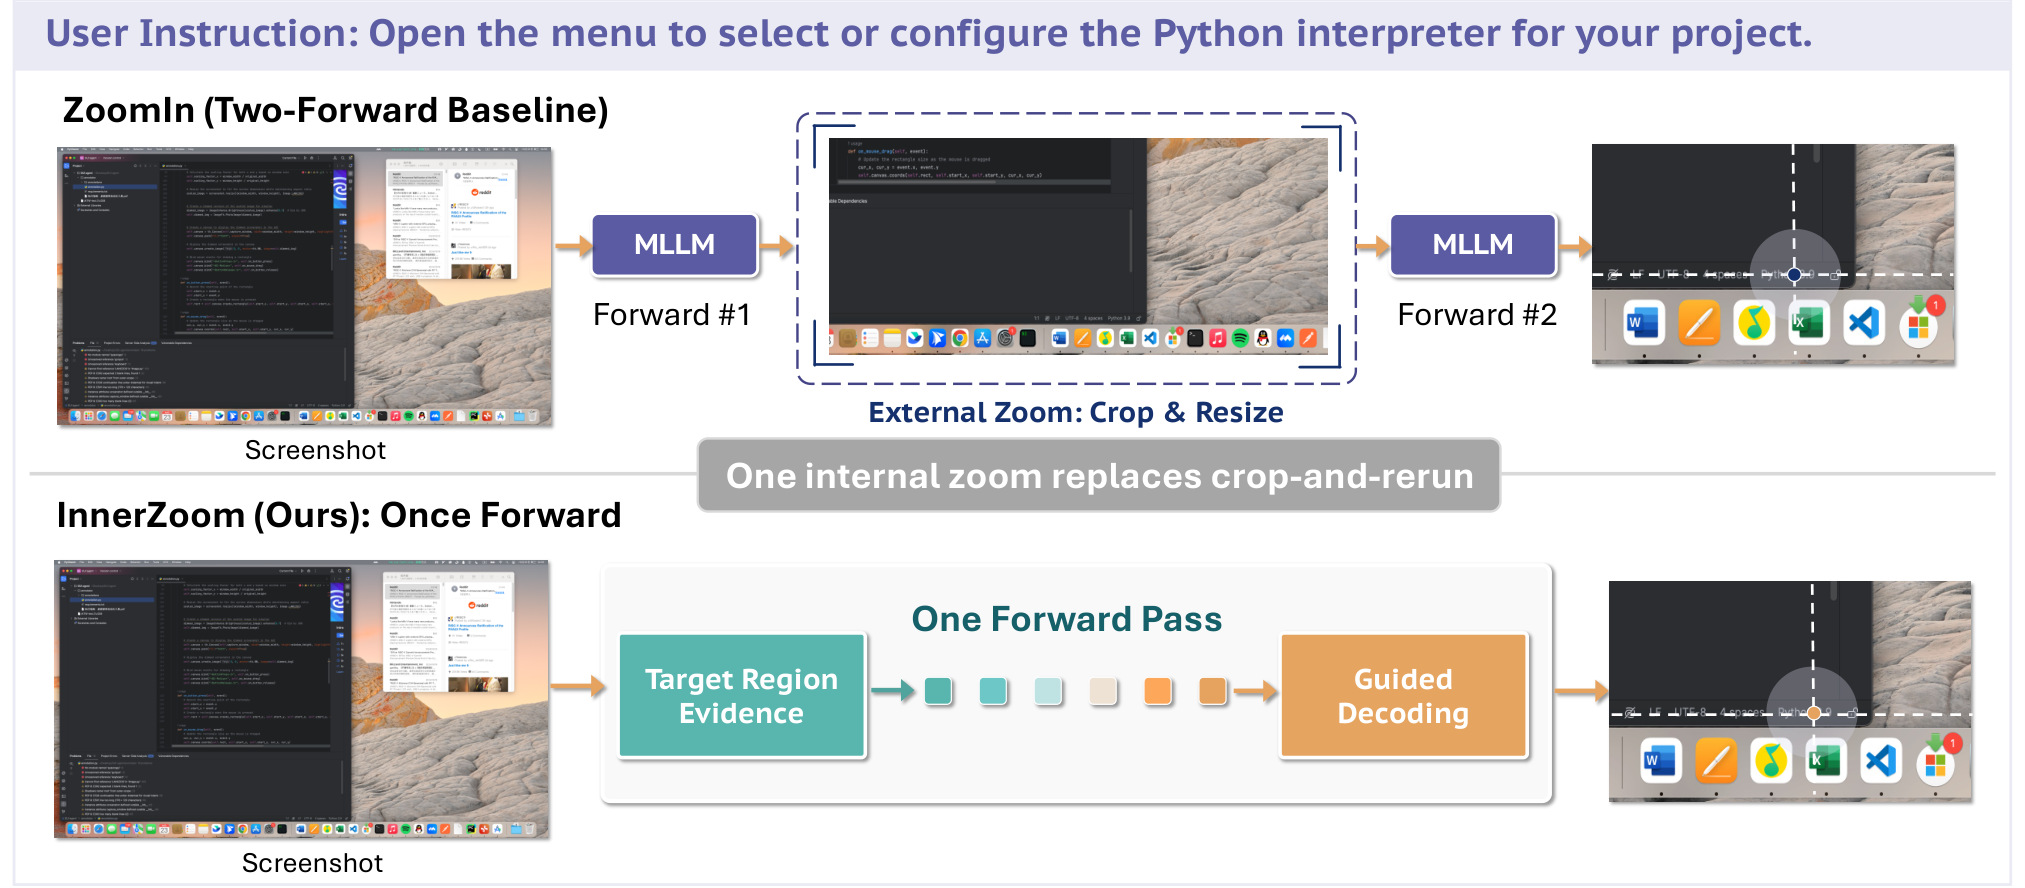
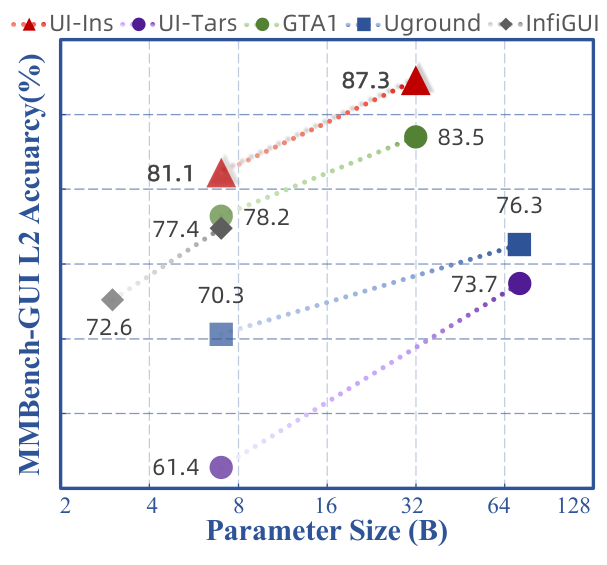
UI-Ins: Enhancing GUI Grounding with Multi-Perspective Instruction as Reasoning

Liangyu Chen, Hanzhang Zhou, Chenglin Cai, Jianan Zhang, Panrong Tong, Xu Zhang, Quyu Kong, Chen Liu, Yuqi Liu, Wenxuan Wang, Yue Wang, Qin Jin, Steven Hoi

Treating diverse instructions as reasoning pathways for more reliable GUI grounding.

Research overview

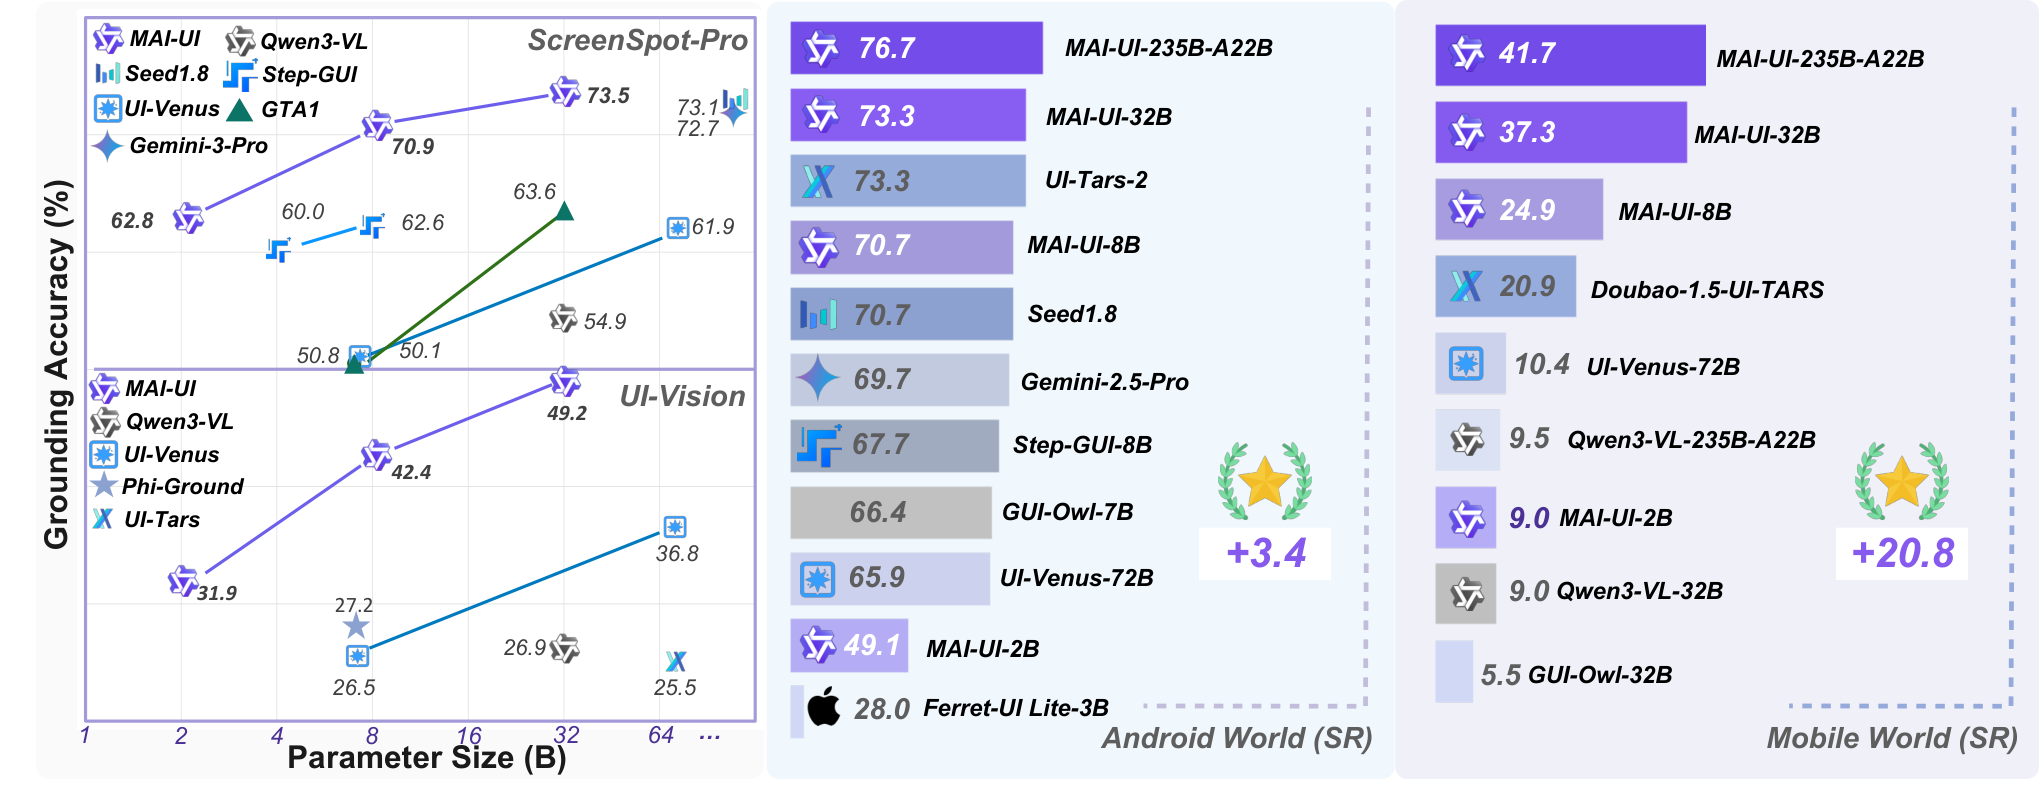
A two-stage approach first learns from diverse instructions, then uses reinforcement learning to select and combine useful perspectives. UI-Ins-7B serves as the executor in an AndroidWorld agent with a reported 74.1% success rate.

ddeseg research figure

Dynamic Derivation and Elimination: Audio Visual Segmentation with Enhanced Audio Semantics

Chen Liu, Liying Yang, Peike Li, Dadong Wang, Lincheng Li, Xin Yu

CVPR 2025First authorPaperCode

Deriving distinct sound semantics and removing irrelevant audio for precise visual grounding.

Research overview

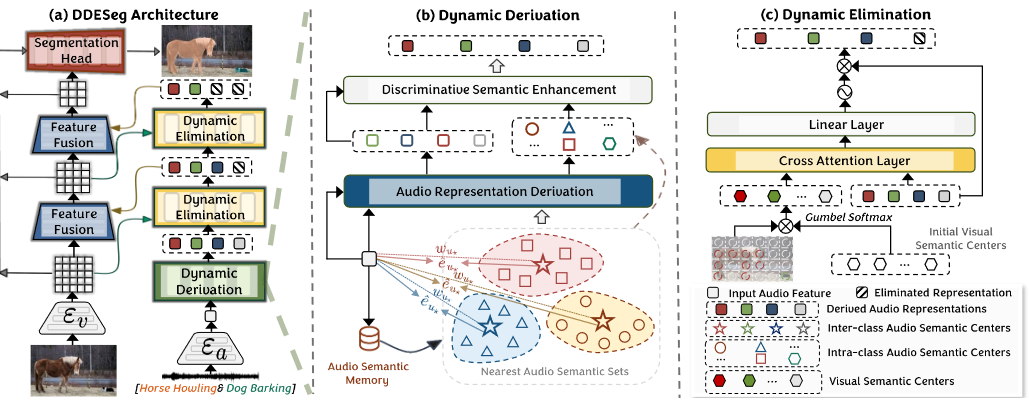
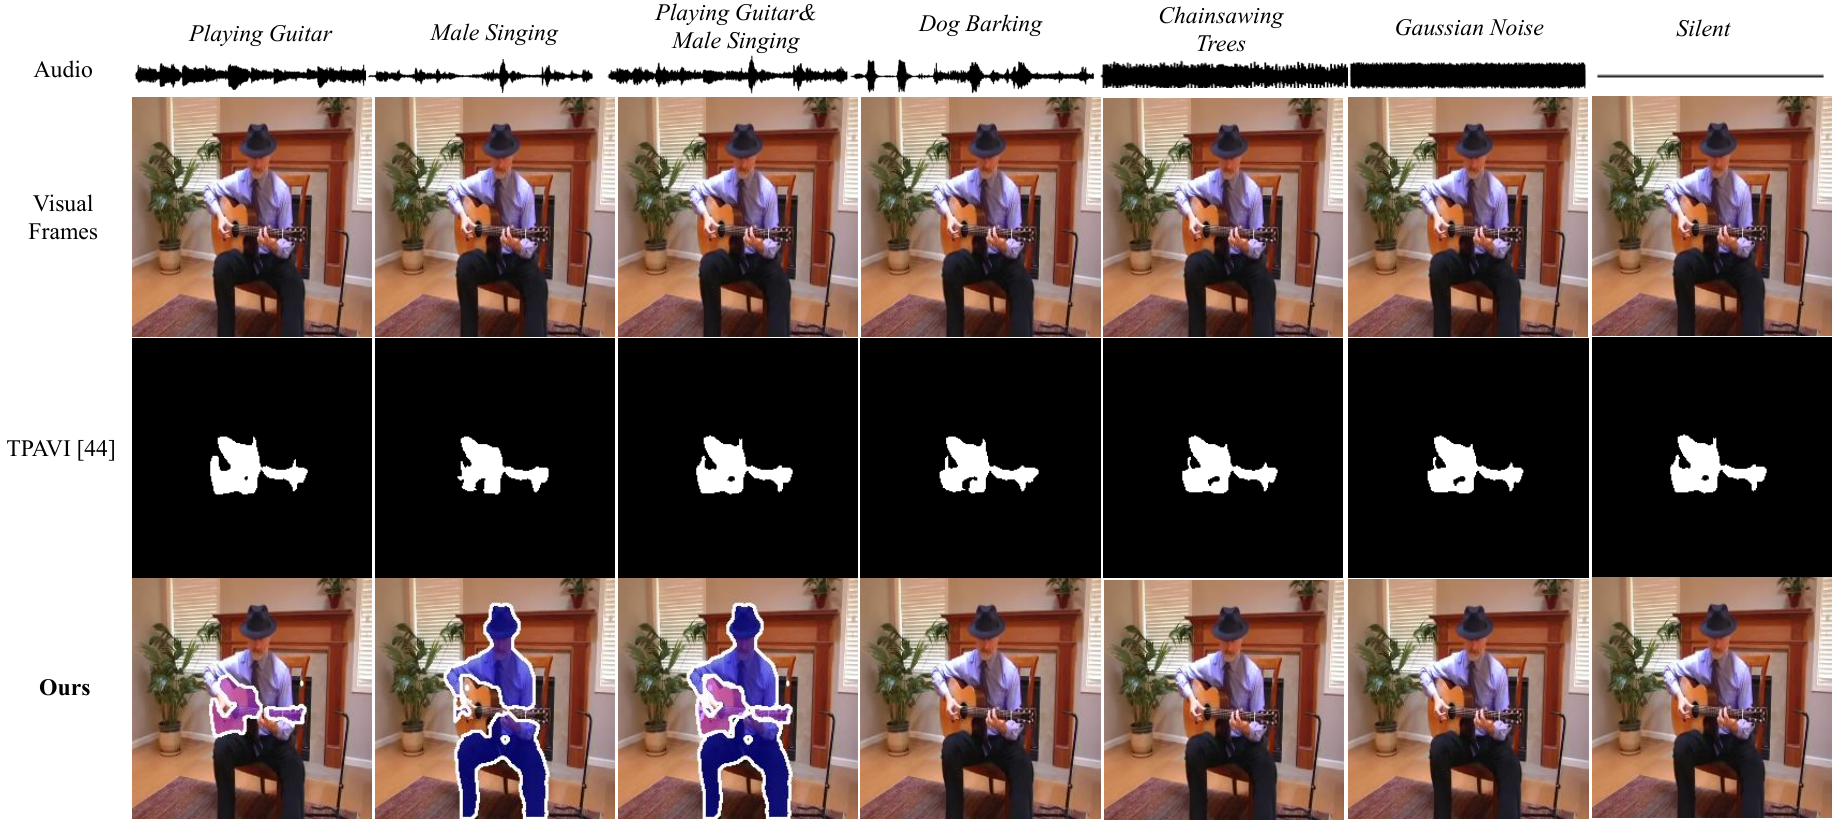
DDESeg addresses overlapping sound sources and variation in the sounds produced by the same object. Semantic derivation enriches source-specific representations, while dynamic elimination removes audio information that does not match visible sounding regions.

ravs research figure

Robust Audio-Visual Segmentation via Audio-Guided Visual Convergent Alignment

Chen Liu, Peike Li, Liying Yang, Dadong Wang, Lincheng Li, Xin Yu

CVPR 2025First authorPaper

Local audio-visual alignment and uncertainty estimation for changing sounding objects.

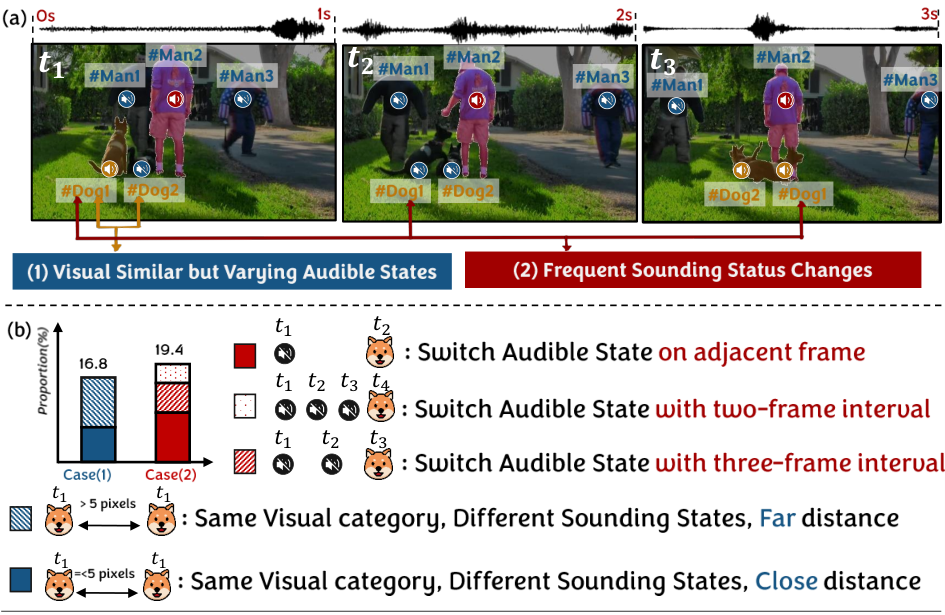
Research overview

Audio-guided interactions group visual features by their response to sound. An uncertainty module accounts for spatial and temporal ambiguity when objects frequently switch between sounding and silent states.

luavs research figure

Benchmarking Audio Visual Segmentation for Long-Untrimmed Videos

Chen Liu, Peike Patrick Li, Qingtao Yu, Hongwei Sheng, Dadong Wang, Lincheng Li, Xin Yu

CVPR 2024First authorPaperProject & dataset

A benchmark for grounding sounding objects across long videos, including silent intervals.

Research overview

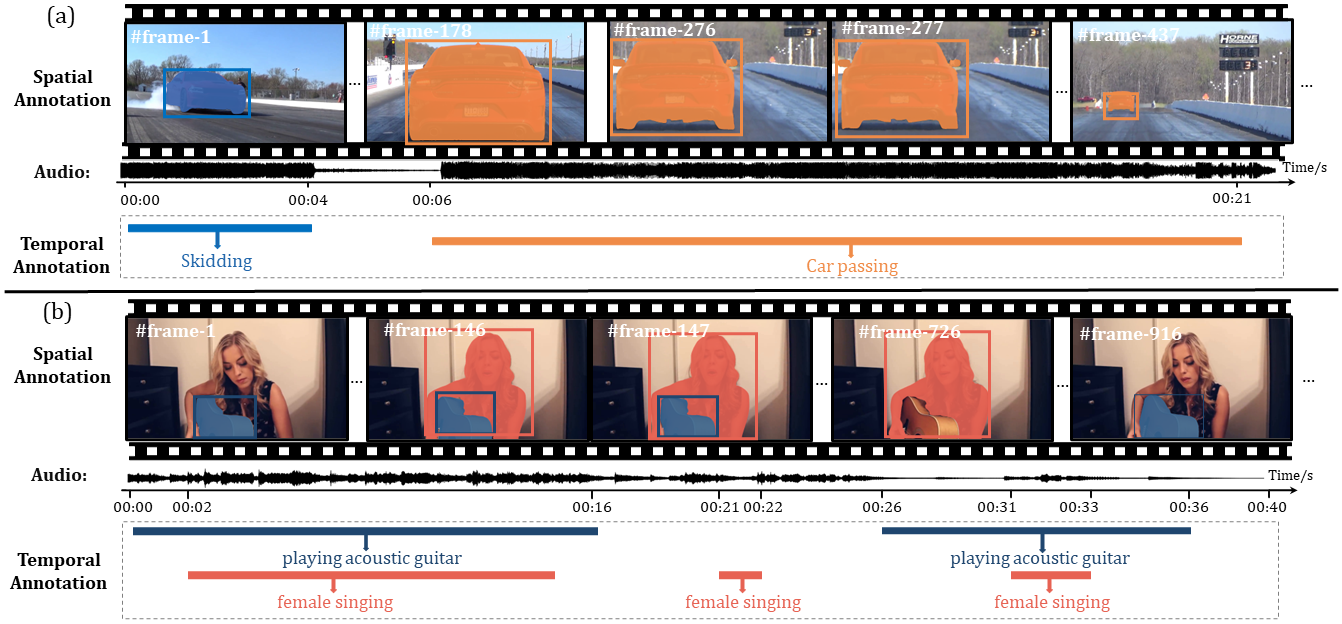
LU-AVS studies where and when objects produce sound in untrimmed videos. Frame-level temporal annotations, segmentation masks and bounding boxes support evaluation beyond short, continuously sounding clips.

freeavatar research figure

FreeAvatar: Robust 3D Facial Animation Transfer by Learning an Expression Foundation Model

Feng Qiu, Wei Zhang, Chen Liu, Rudong An, Lincheng Li, Yu Ding, Changjie Fan, Zhipeng Hu, Xin Yu

SIGGRAPH Asia 2024PaperCode

Learning an expression representation to transfer subtle facial motion across 3D avatars.

Research overview

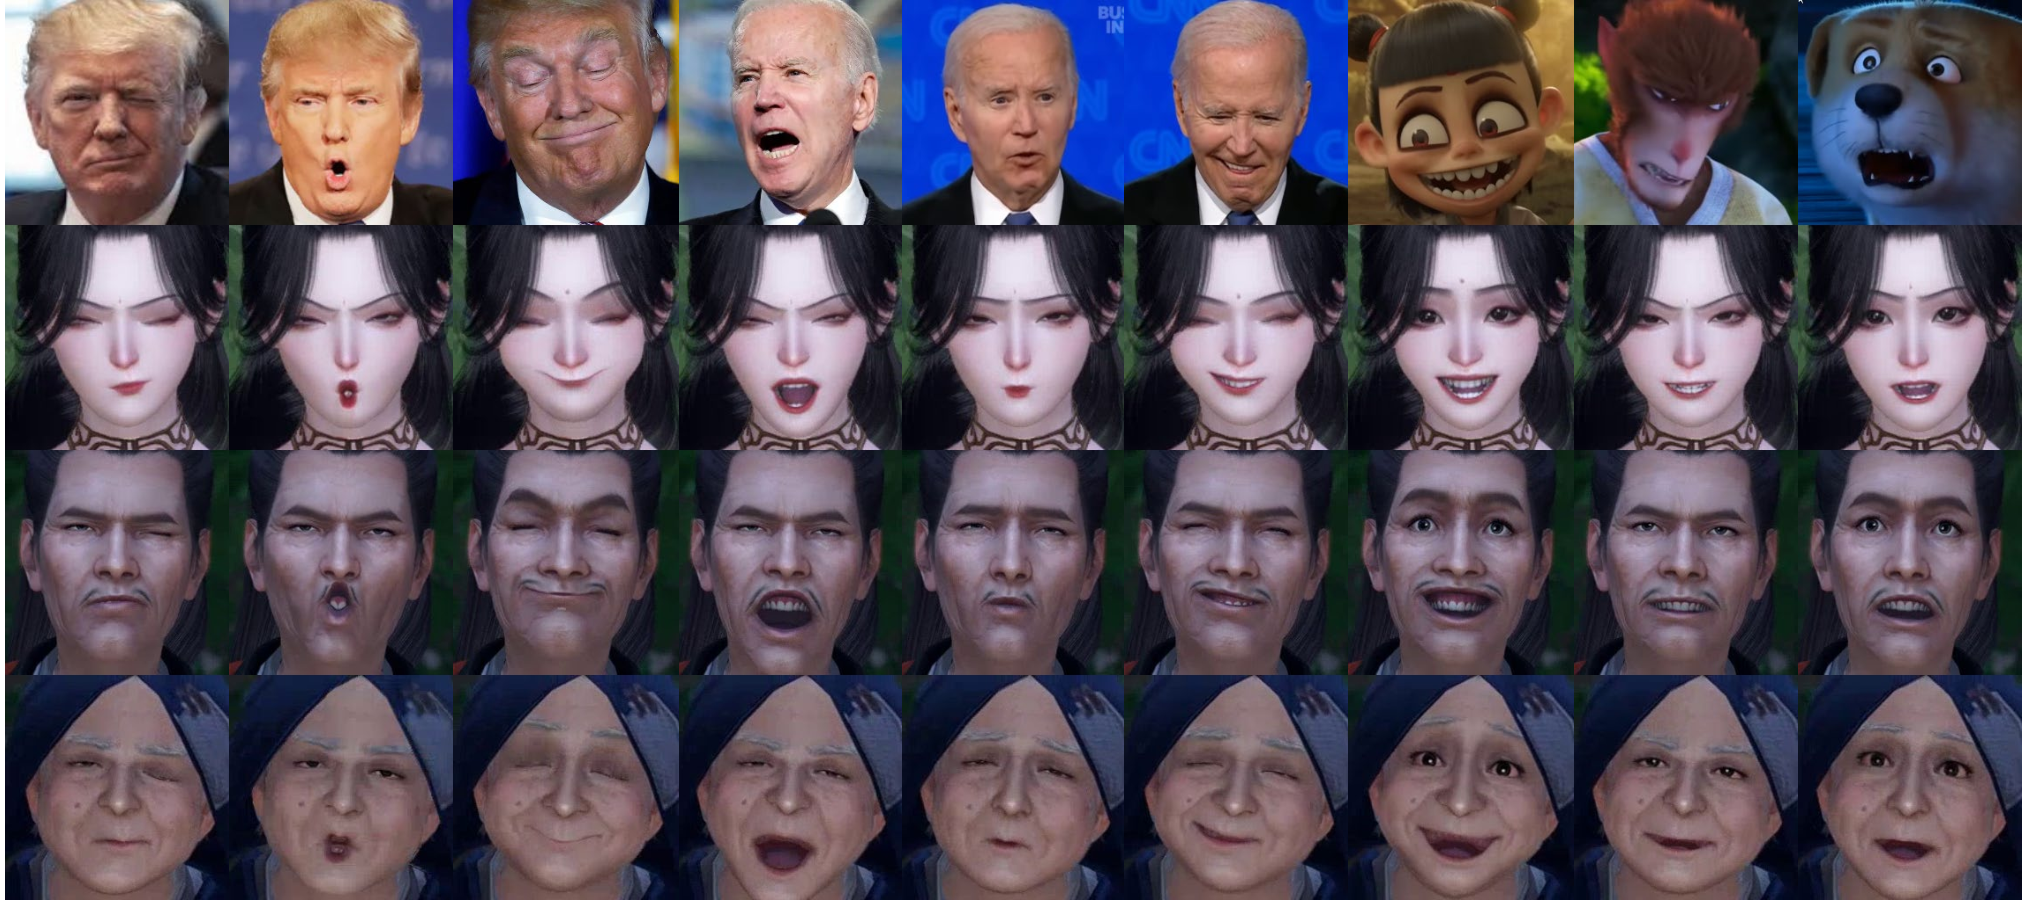
FreeAvatar combines an expression foundation model with a multi-avatar animation model. Learned expression features provide perceptual supervision, helping capture fine-grained expressions without relying on geometric constraints.

bavs research figure

BAVS: Bootstrapping Audio-Visual Segmentation by Integrating Foundation Knowledge

Chen Liu, Peike Li, Hu Zhang, Lincheng Li, Zi Huang, Dadong Wang, Xin Yu

IEEE TMM 2024First authorPaperProject

Combining visual masks and audio semantics to suppress background noise and off-screen sounds.

Research overview

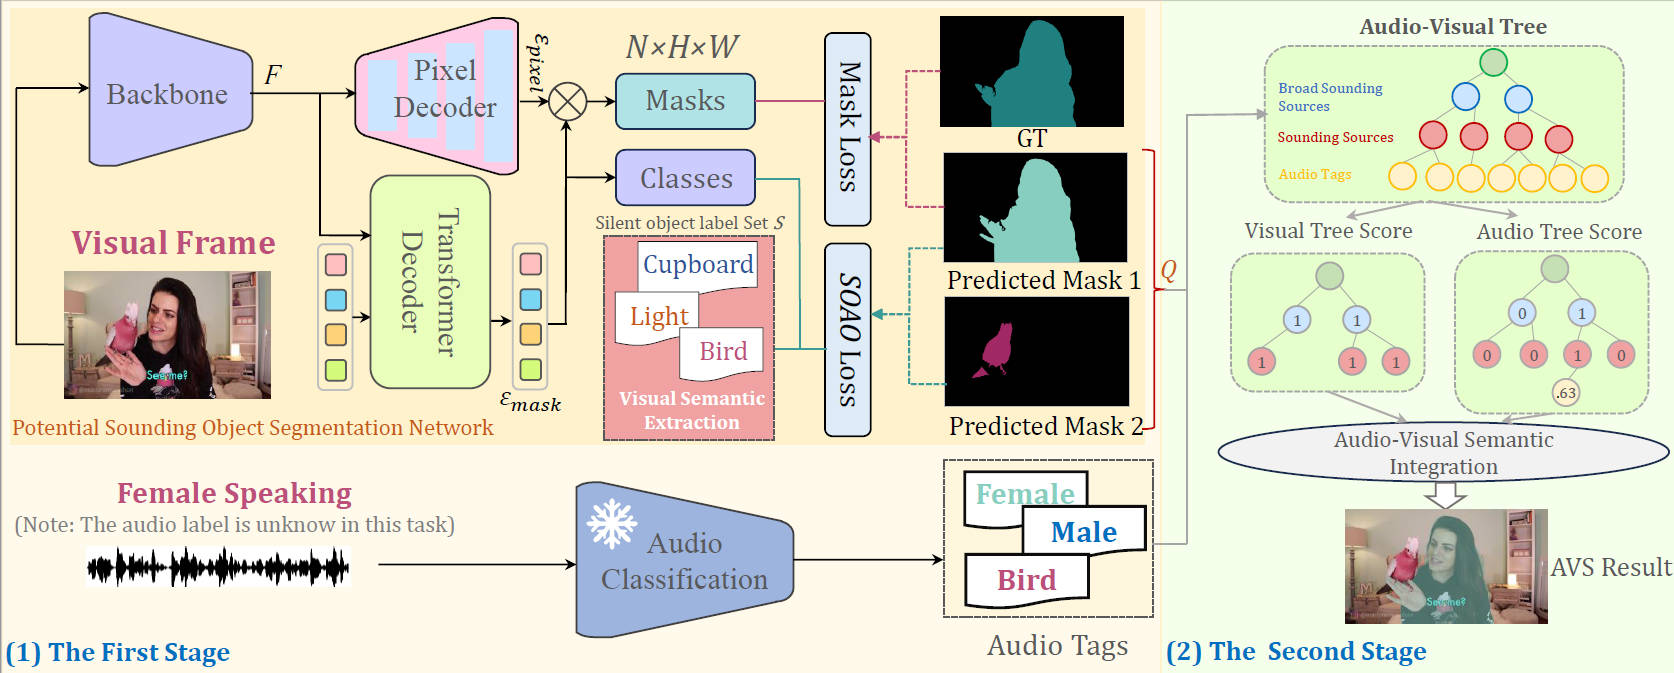
A two-stage framework first identifies potential sounding objects and audio categories. An audio-visual semantic integration strategy then associates these predictions through a hierarchical audio-visual tree.

avsc research figure

Audio-Visual Segmentation by Exploring Cross-Modal Mutual Semantics

Chen Liu, Peike Li, Xingqun Qi, Hu Zhang, Lincheng Li, Dadong Wang, Xin Yu

ACM MM 2023First authorPaper

Learning audio-visual semantic correspondence to distinguish sounding objects from silent distractors.

Research overview

A silent-object-aware objective reduces visual saliency bias. Audio category scores are associated with potential object masks to establish cross-modal semantic correspondence.

Research Experience

University of Technology Sydney

Postdoctoral Research Associate · Australian Artificial Intelligence Institute

Current

Research Internships

Alibaba Tongyi Lab

Research internship

Mentors: Yue Wang, Hanzhang Zhou and Steven Hoi

2025
NetEase Fuxi AI Lab

Research internship

Mentor: Lincheng Li

2024
CSIRO Data61

Research internship

Mentor: Dadong Wang

2023

Education

The University of Queensland

Ph.D. · Object-Centric Audio-Visual Alignment for Sounding Source Segmentation

2022–2025
Northwest A&F University

Master’s degree

2019–2022

Awards & Competitions

Academic Service

Teaching Experience